Matching & Tracking
- Matching(匹配)主要指的是在 不同 的图像中找到相同的对象或特征。
- Tracking(跟踪)主要指的是在 视频序列 或 一系列连续 的图像中跟踪对象的位置和状态。
它们在概念上有重叠,但各自解决的问题和使用的技术有所不同。Tracking 通常需要在视频的连续帧中识别和跟踪对象。为了实现这一点,需要在不同帧之间匹配对象或特征。因此,matching 可以被看作是 tracking 过程中一个重要的步骤。例如,在目标跟踪算法中,可能会使用特征匹配来识别同一对象在连续帧中的位置,也有某些跟踪算法(如 Kalman 滤波器或均值漂移算法)主要依赖运动模型和统计特性,而不需要特征匹配。Matching 可以独立于 Tracking 使用。它主要用于静态图像中的对象识别和特征提取。例如,图像拼接、图像检索和物体识别等任务。
SAM
- Image encoder: A heavy ViT-based backbone for feature extraction.
- Prompt encoder: Modeling the positional information from the interactive points, box, or mask prompts.
- Mask decoder: A transformer-based decoder takes both the extracted image embedding with the concatenated output and prompt tokens for final mask prediction.
Matching Anything by Segmenting Anything
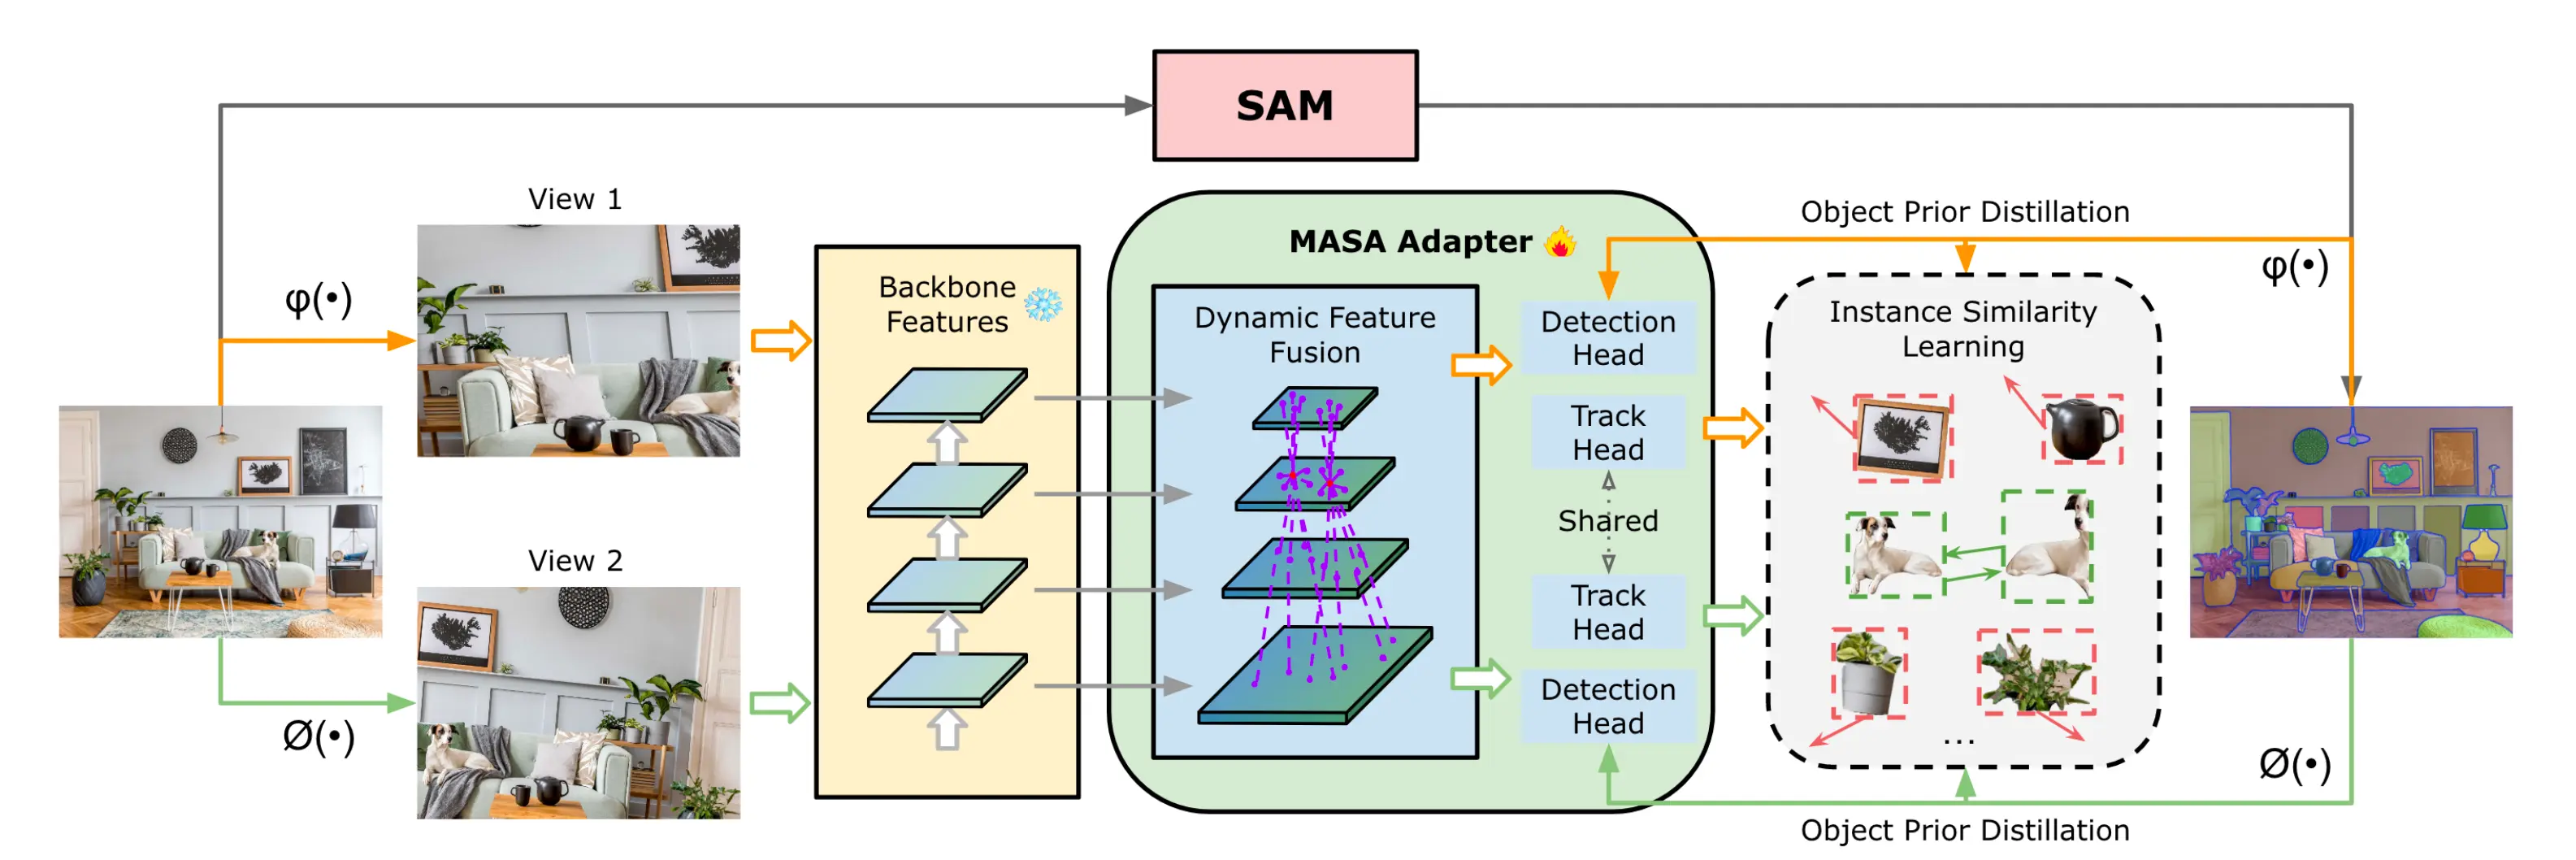
MASA Pipeline
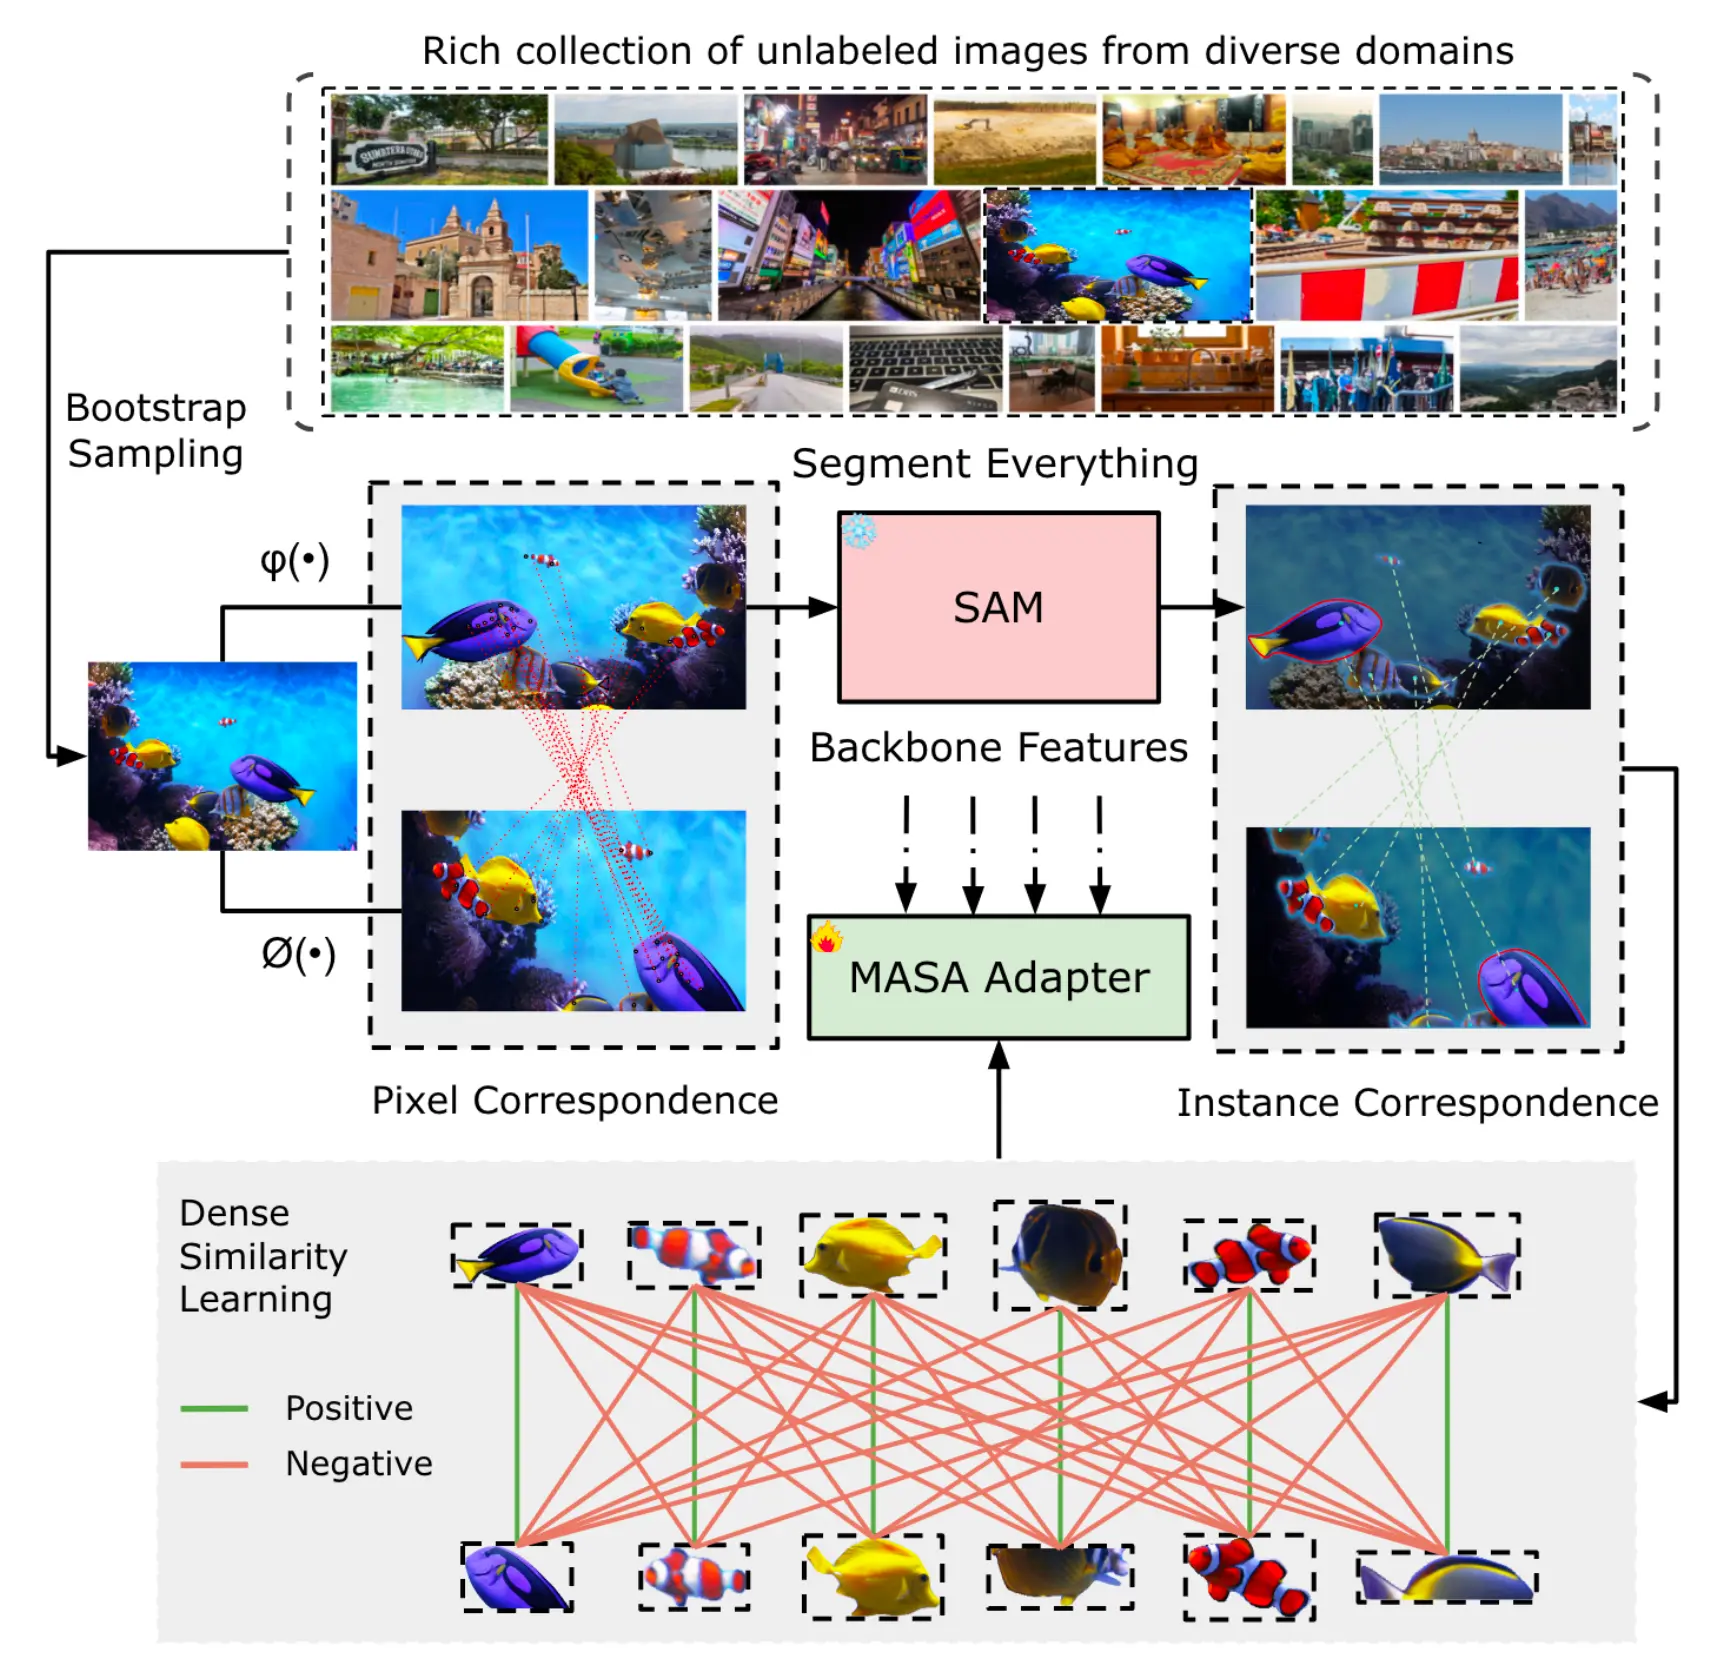
- Construct a rich collection of raw images from diverse domains to prevent learning domainspecific features.
- Adopting two different strong data augmentations on the same image.
- SAM’s exhaustive segmentation of the entire images automatically yields a dense and diverse collection of instance proposals .
- Use the contrastive learning formula to learn a discriminative contrastive embedding space.
MASA Adapter
However, as not all pretrained features are inherently discriminative for tracking, we first transform these frozen backbone features into new features more suitable for tracking.
Given the diversity in shapes and sizes of objects, we construct a multi-scale feature pyramid. For hierarchical backbones like the Swin Transformer in Detic and Grounding DINO, we directly employ FPN. For SAM, which utilizes a plain ViT backbone, we use Transpose Convolution and MaxPooling to upsample and downsample the single-scale features of stride 16× to produce hierarchical features with scale ratios of 1/4, 1/8, 1/16 , 1/32. To effectively learn discriminative features for different instances, it’s essential that objects in one location are aware of the appearances of instances in other locations. Hence, we use deformable convolution to generate dynamic offsets and aggregate information across spatial locations and feature levels. For SAM-based models, we additionally use taskaware attention and scale-aware attention from Dyhead, since the detection performance is important for accurate auto mask generation.
Extract instance-level features by applying RoI-Align to the visual features , followed by processing with a lightweight track head comprising 4 convolutional layers and 1 fully connected layer to generate instance embeddings. Object prior distillation branch as an auxiliary task during training. This branch employs a standard RCNN detection head to learn bounding boxes that tightly encompass SAM’s mask predictions for each instance. It effectively learns exhaustive object location and shape knowledge from SAM and distils this information into the transformed feature representations. This design not only strengthens the features of the MASA adapter, resulting in improved association performance but also accelerates SAM’s everything mode by directly providing the predicted box prompts.
Inference
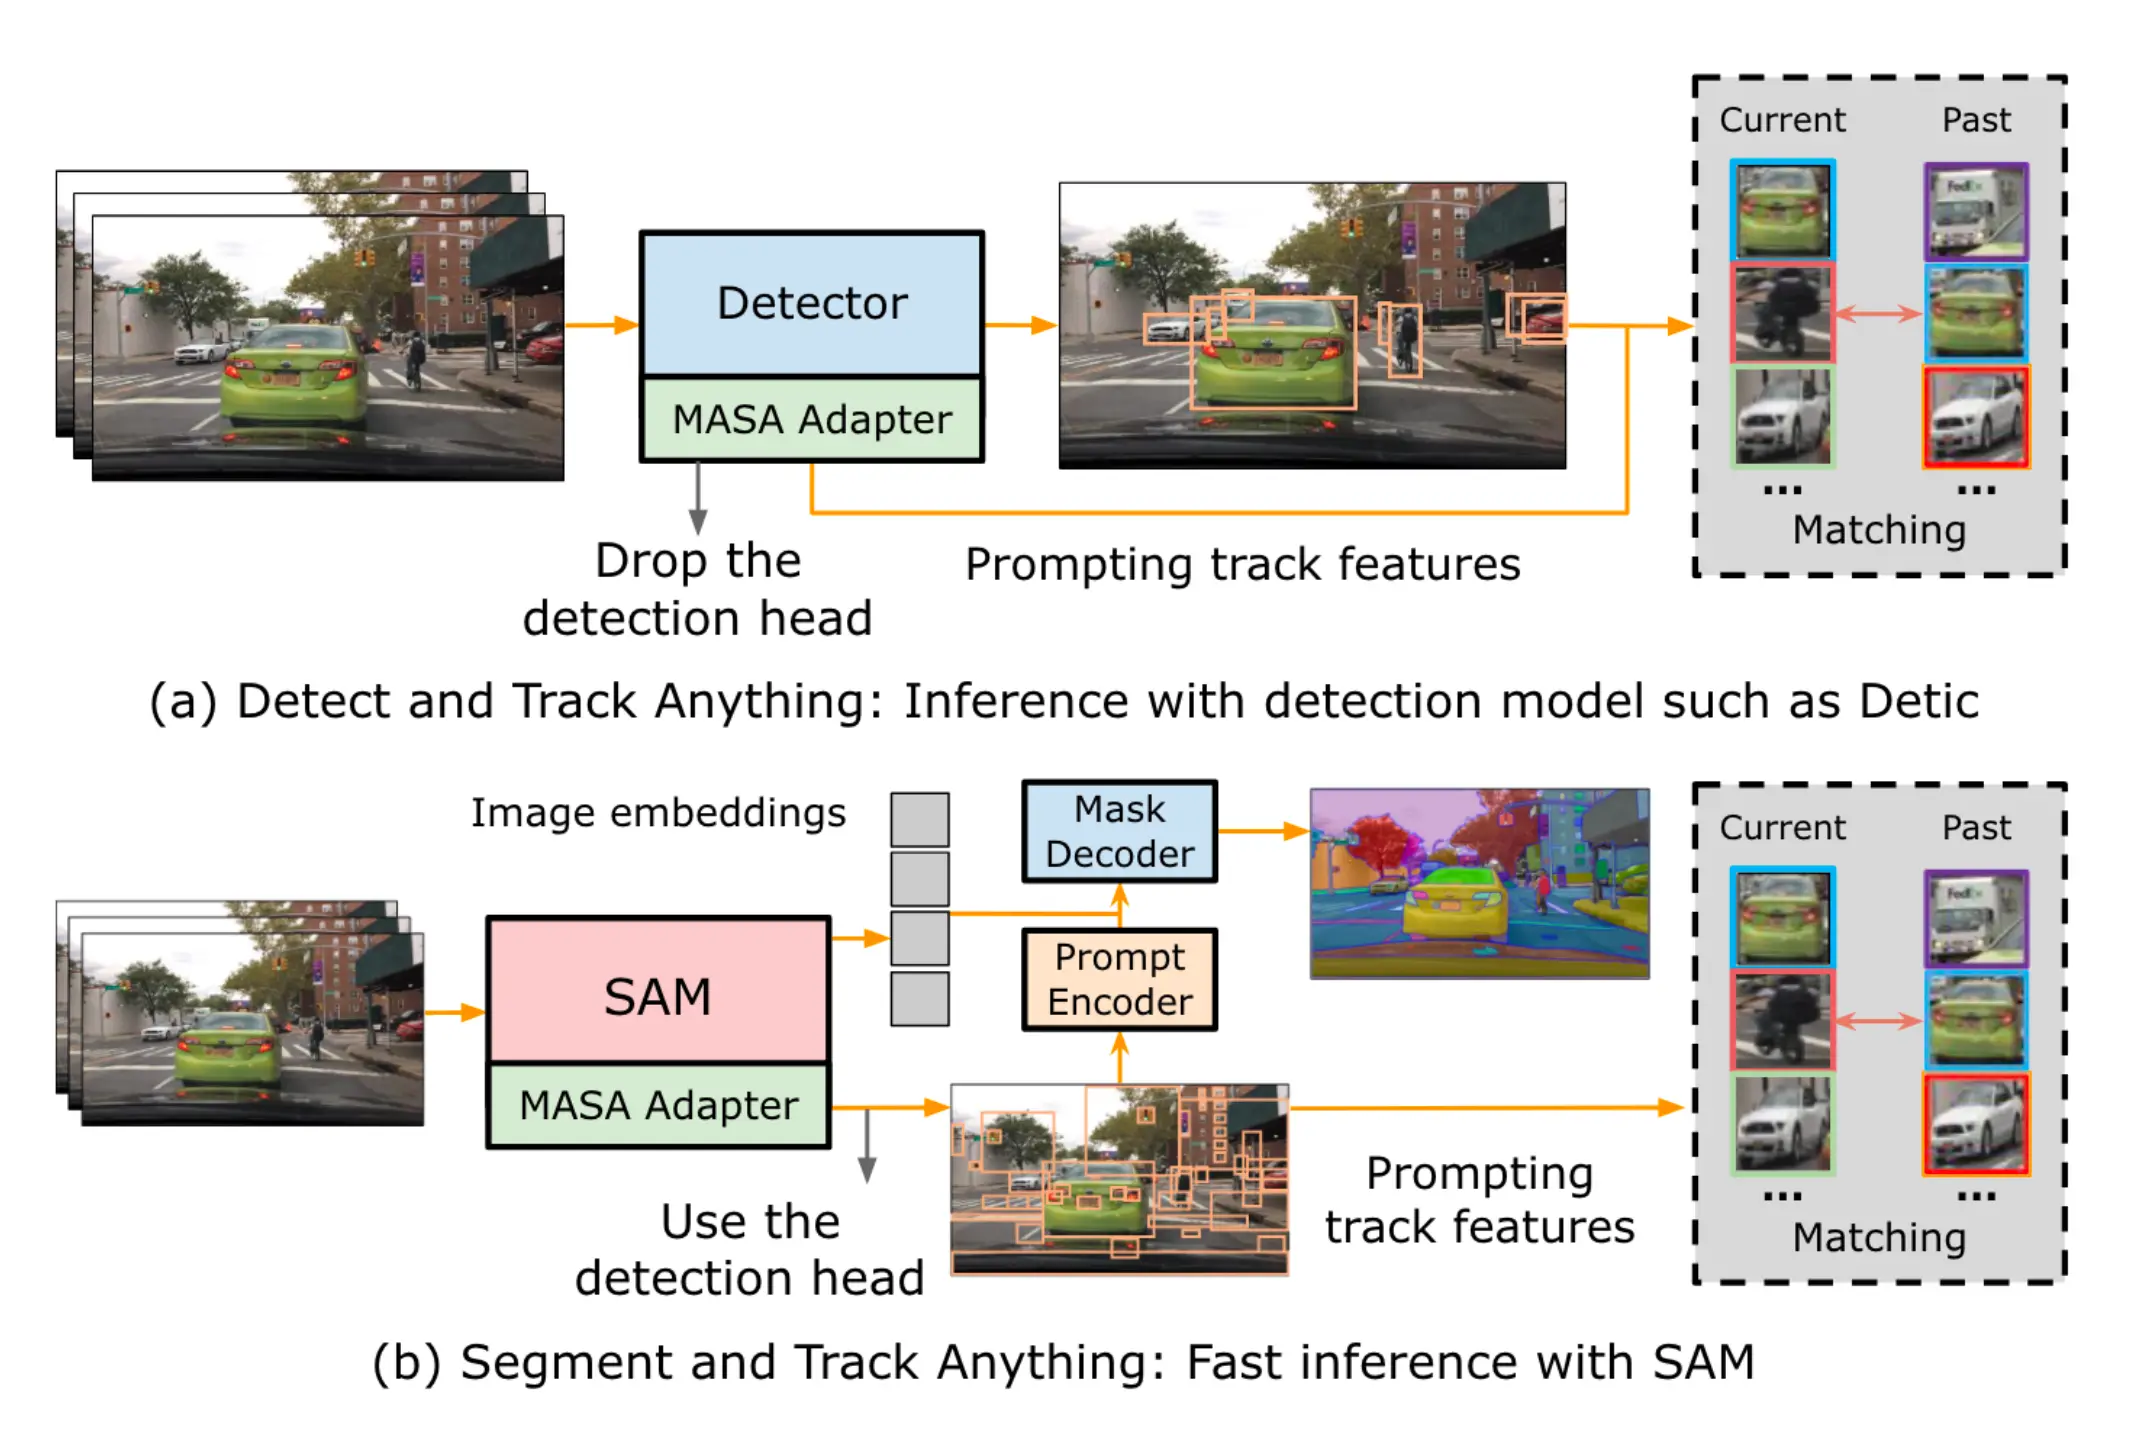
Detect and Track Anything
- Remove the MASA detection head that was learned during training.
- MASA adapter then solely serves as a tracker.
- The detectors predict the bounding boxes, and then they are utilized to prompt the MASA adapter, which retrieves corresponding tracking features for instance matching.\
Segment and Track Anything
- Keep the detection head to predict all potential objects within a scene.
- Forwarding box predictions as prompts to both the SAM mask decoder and the MASA adapter for segmenting and tracking everything.
复现
原文样例
视频附件
msora_fish_10s_outputs.mov仅包含语雀内部资源 ID(inputs/prod/yuque/2024/33664725/mov/1719382563270-a82e86c6-ace6-4b77-b996-b402a7b73445.mov),导出包未提供可直接下载地址。
长隆海洋馆数据
密集复杂场景
视频附件
dense_chimelong_outputs.mov仅包含语雀内部资源 ID(inputs/prod/yuque/2024/33664725/mov/1719382732268-f08377b1-9f99-40ed-8022-44494bf83b51.mov),导出包未提供可直接下载地址。
稀疏简单场景
视频附件
sparse_chimelong_outputs.mov仅包含语雀内部资源 ID(inputs/prod/yuque/2024/33664725/mov/1719382753013-de1434bd-b107-4452-8c77-e0f2ea9678a6.mov),导出包未提供可直接下载地址。